往期Archive · 2026
史料会说话,AI 会听吗?——从木橱、卡片到大模型的历史检索术Sources Speak, but Does AI Listen? Historical Search from Card Catalogues to Large Language Models
Sources Speak, but Does AI Listen? Historical Search from Card Catalogues to Large Language Models史料会说话,AI 会听吗?——从木橱、卡片到大模型的历史检索术
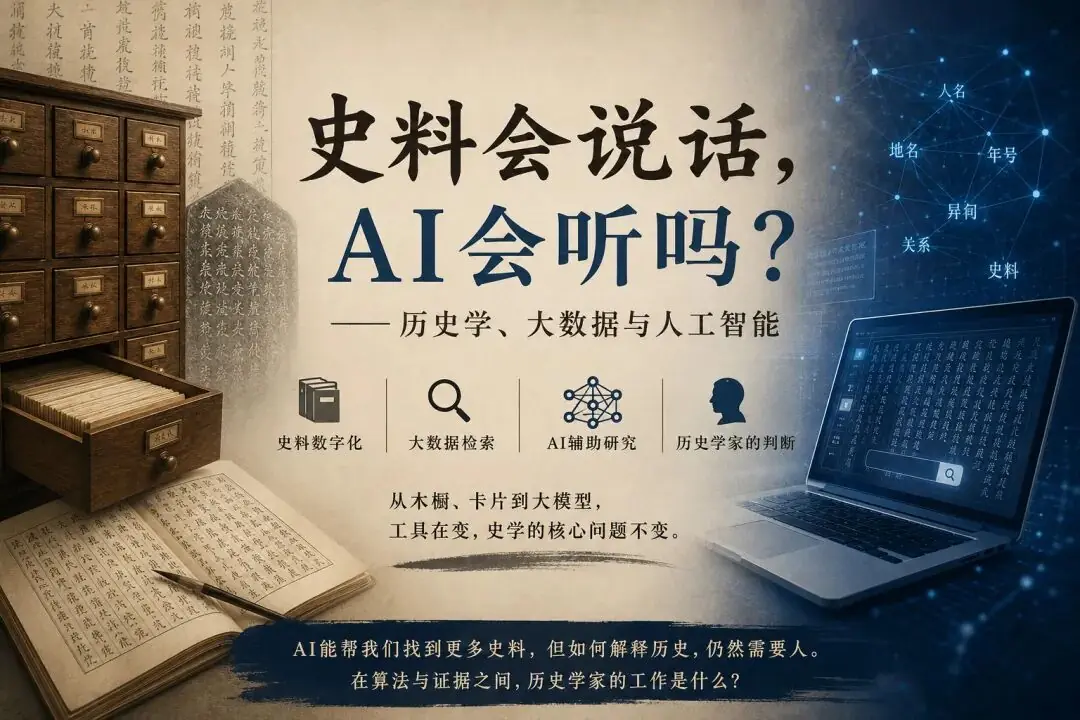
过去的历史学家如何查史料?有人靠书柜,有人靠卡片,有人靠笔记本,也有人像李焘编《续资治通鉴长编》那样,用一套巨大的木橱系统来安放材料。到了今天,二十四史、地方志、档案、碑刻、图像材料正在被电子化。OCR、HTR、ElasticSearch、RAG、Agent……这些听起来属于计算机世界的工具,正在进入历史研究的工作流。 但问题也随之出现:搜索引擎真的“懂”史料吗?AI 会不会编造不存在的材料?“秦王世民”“太宗”“李世民”在机器眼里是不是同一个人?古今地名、年号换算、避讳、异名、误识别,又该如何处理? 这不是一次关于“AI 取代历史学家”的技术宣传。我们更关心的是:当史料越来越容易被搜索、被切分、被向量化、被模型调用时,历史学本身的问题是否发生了变化?
How did historians of the past look up their sources? Some relied on bookcases, some on index cards, some on notebooks, and some, like Li Tao when compiling the Long Draft Continuation of the Comprehensive Mirror for Aid in Government, used a vast system of wooden cabinets to store their materials. Today the Twenty-Four Histories, local gazetteers, archives, inscriptions and visual materials are being digitised. OCR, HTR, ElasticSearch, RAG, agents... tools that sound as if they belong to the world of computing are entering the workflow of historical research. But problems come with them: does a search engine really "understand" historical sources? Will AI fabricate sources that do not exist? Are "Shimin, Prince of Qin", "Taizong" and "Li Shimin" the same person in a machine's eyes? And how should we handle old and modern place names, conversions between reign titles, taboo characters, variant names and recognition errors? This is not a technical sales pitch about "AI replacing historians". What concerns us more is this: as historical sources become ever easier to search, segment, vectorise and feed to models, have the questions of history itself changed?
The notes below are in Chinese, as the talks are.
预告Announcement
史料会说话,AI 会听吗?——从木橱、卡片到大模型的历史检索术
2026-05-21
过去的历史学家如何查史料?有人靠书柜,有人靠卡片,有人靠笔记本,也有人像李焘编《资治通鉴长编》那样,用一套巨大的木橱系统来安放材料。史料浩如烟海,问题从来不只是“有没有读到”,更是“如何找到、如何分类、如何互相印证”。到了今天,二十四史、地方志、档案、碑刻、图像材料正在被电子化。OCR、HTR、ElasticSearch、Kibana、RAG、Agent……这些听起来属于计算机世界的工具,正在进入历史研究的工作流。它们能让我们几秒钟检索海量文本,也能帮助发现人名、地名、时间和概念之间的关联。但问题也随之出现:搜索引擎真的“懂”史料吗?AI 会不会编造不存在的材料?“秦王世民”“太宗”“李世民”在机器眼里是不是同一个人?古今地名、年号换算、避讳、异名、误识别,又该如何处理?本次沙龙将围绕“历史学、大数据与人工智能”展开,讨论从传统史料检索到数字化处理,再到 AI 辅助研究的几个关键环节。我们会用一些具体例子,比如《少林寺碑》、二十四史检索、史料结构化回答等,看看人工智能究竟能帮历史研究做到什么,又有哪些地方仍然需要历史学家的判断、怀疑和解释。这不是一次关于“AI 取代历史学家”的技术宣传,也不是一次抽象的未来学讨论。我们更关心的是:当史料越来越容易被搜索、被切分、被向量化、被模型调用时,历史学本身的问题是否发生了变化?欢迎带着问题来:你平时怎么查史料?你相信 AI 给出的历史回答吗?你觉得历史研究中最难被机器替代的部分是什么?